Inference Is Becoming an Ownership Problem
Why enterprises will move from renting model access to controlling their own inference, and the layer that is still missing
Part 1 out of 3
In brief. This year, inference is set to outspend training on AI cloud infrastructure, and it is the part of the stack enterprises control least. The answer is not to own every GPU. It is to own the decisions: which model runs, where, in what configuration, against what service objective. The layer that makes those decisions does not yet exist in mature form, and the discipline that needs it, inference engineering, is just forming.
In July, Ito published what happened when it moved its largest AI workload, a test-running agent that consumes roughly 100 billion tokens a week, from GPT-5.3-Codex to MiniMax M3. Median LLM cost per pipeline run fell 55 percent. But median step time rose from 23 to 29 minutes, the failure rate nearly doubled to 4.5 percent, and the cheaper model needed 23 percent more turns and 2.5 times the tokens. Savings ranged from 81 percent on some repositories to 13 percent on others.1 Ito kept the cheaper model; for its workload, the tradeoff was worth it. For a customer-facing agent, it might not have been.
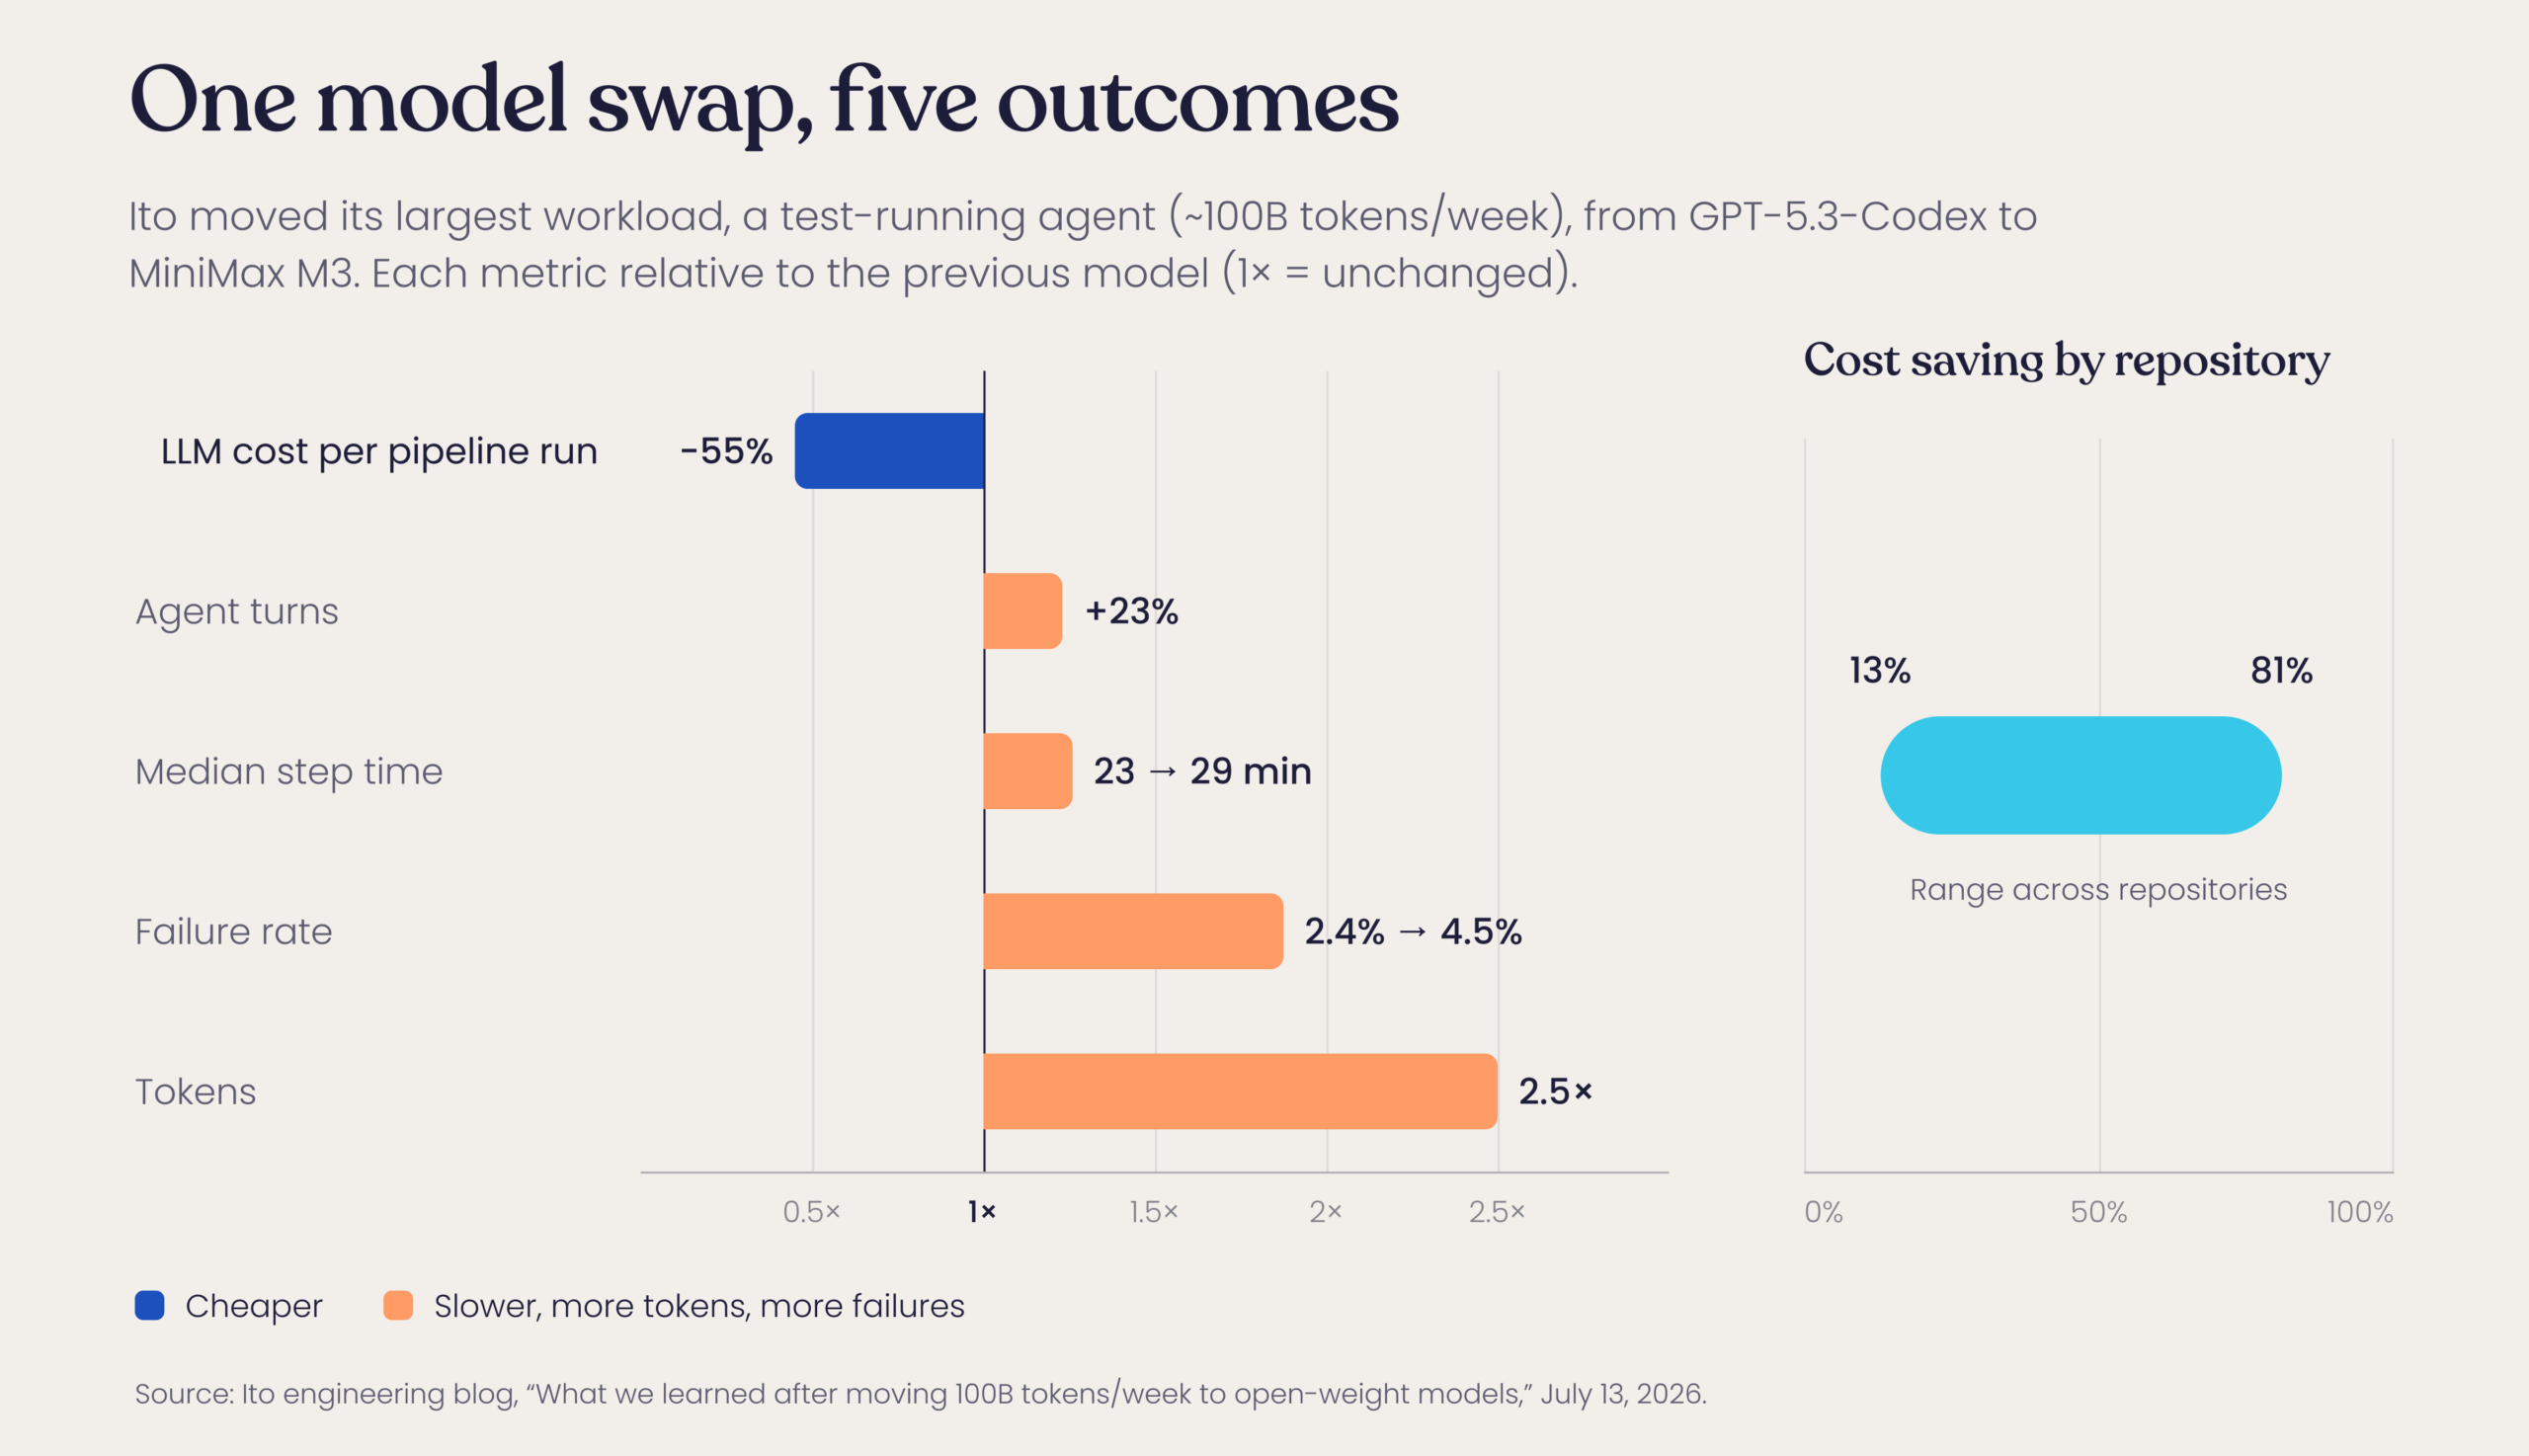
Figure 1. One model swap, five outcomes. Savings varied widely by repository.
The second result came from a lab. Researchers at Microsoft and the University of Illinois held a cluster’s model fixed and kept reconfiguring the cluster as load shifted: instance count, how the model was split across GPUs, and GPU clock speed. Cost to the customer fell 61 percent and energy use 53 percent, while latency targets held.2
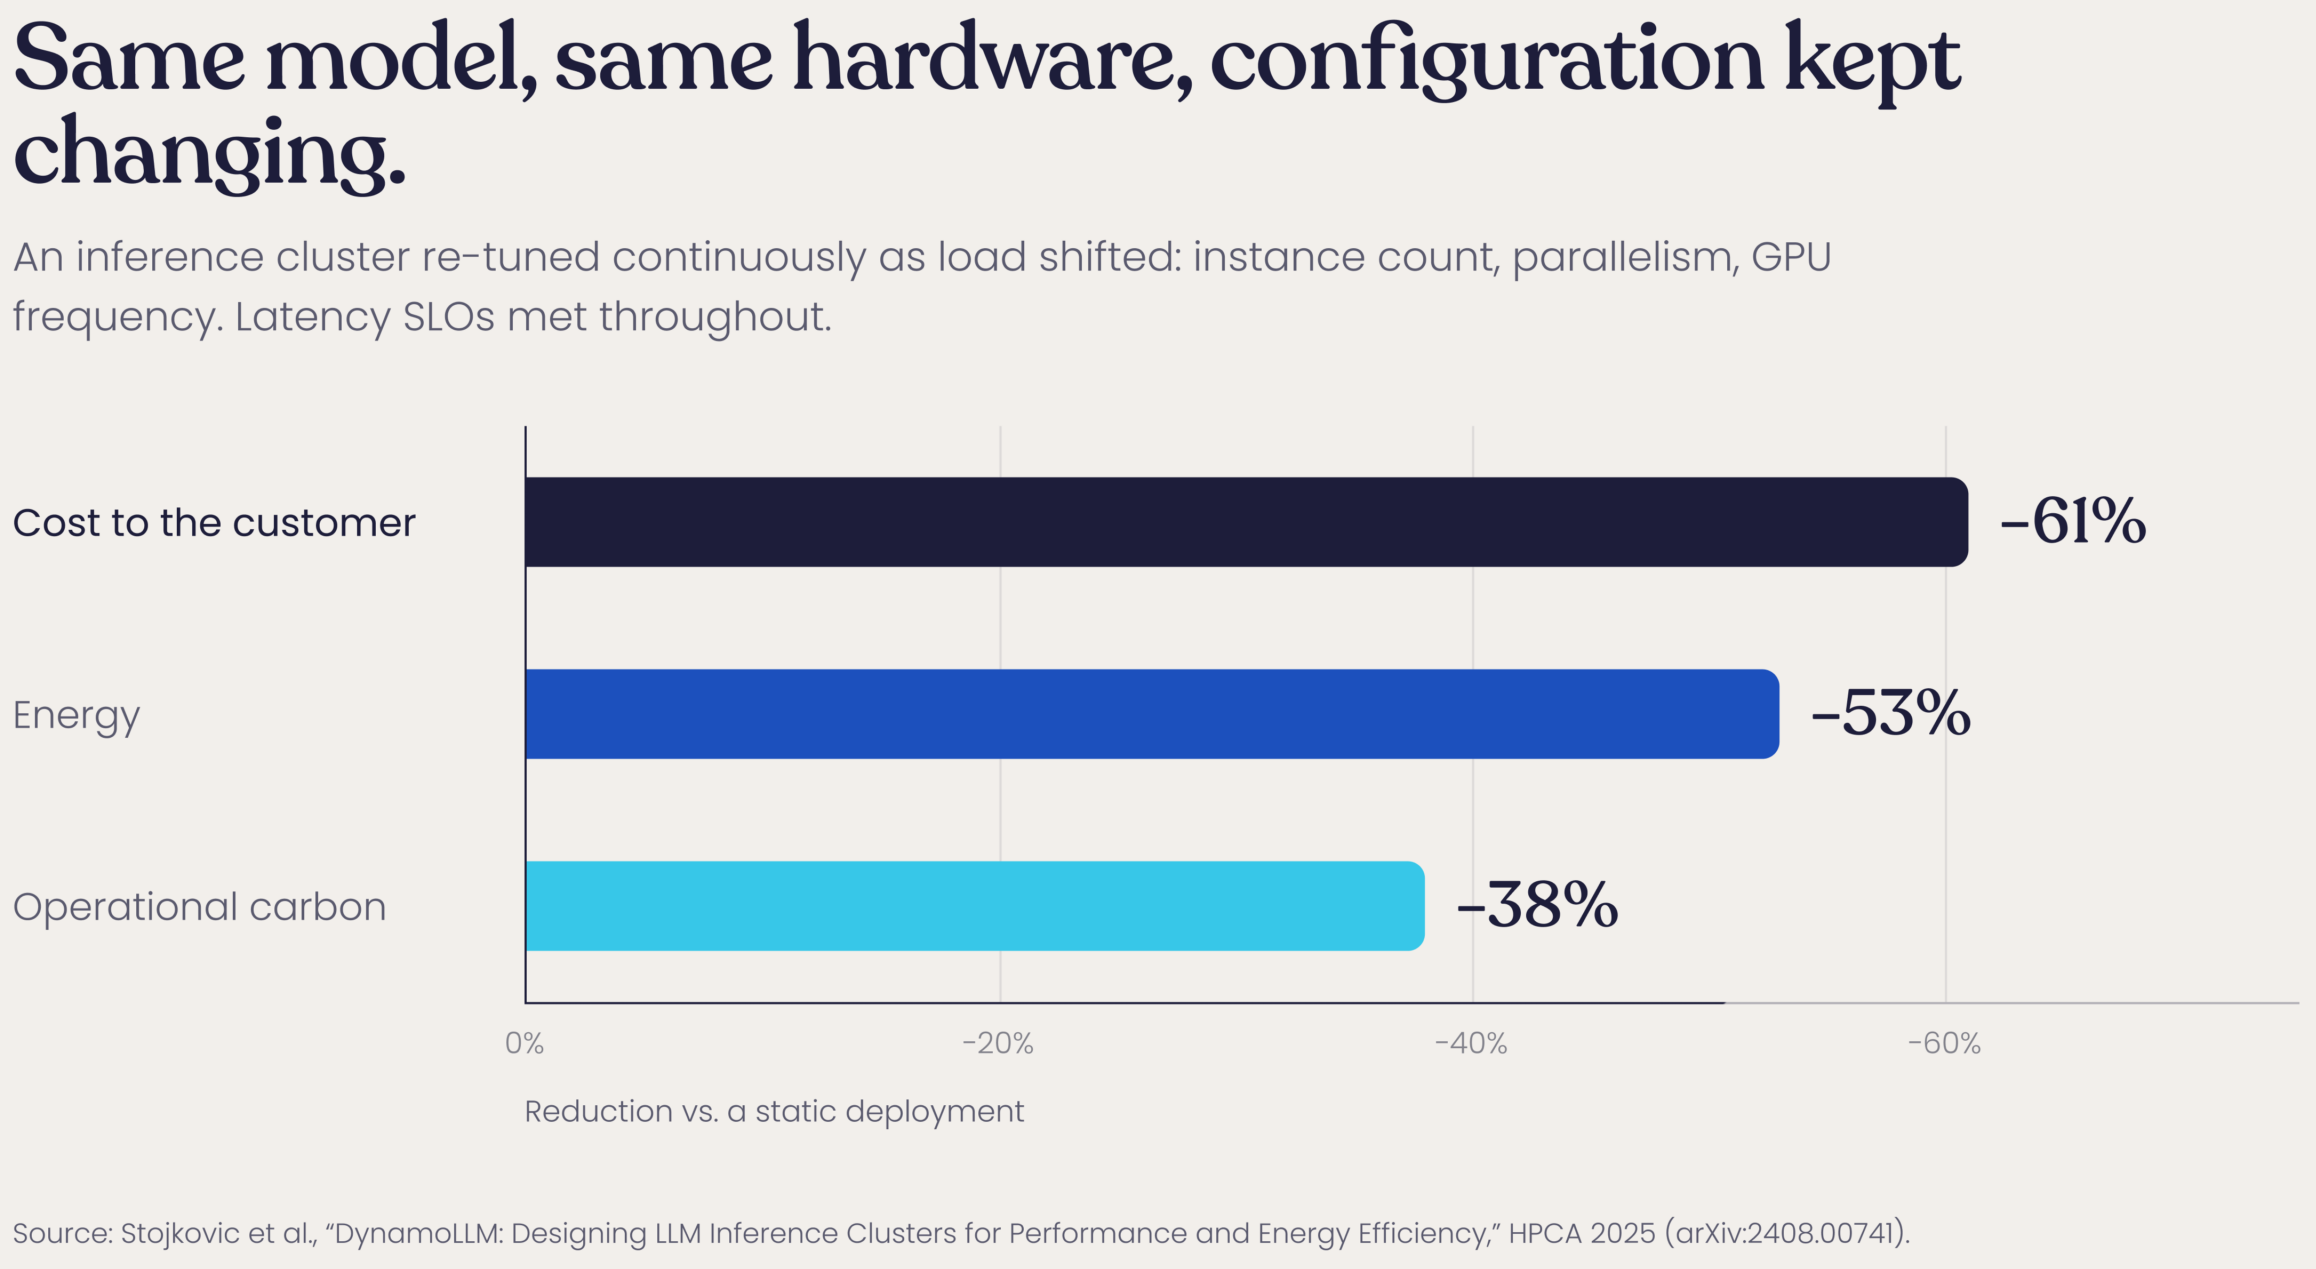
Figure 2. What continuous reconfiguration recovered, with the same model on the same hardware.
Two results, two levers: which model runs, and how the hardware runs it. For many enterprises, getting a return on AI now takes continuous decisions about both, made against a target for cost, latency, and quality. The first phase of enterprise AI hid those decisions behind an endpoint, which suited experimentation. In production, inference shapes both product quality and operating cost, and a change to one can sharply move the other. Few organizations have a system for making them yet.
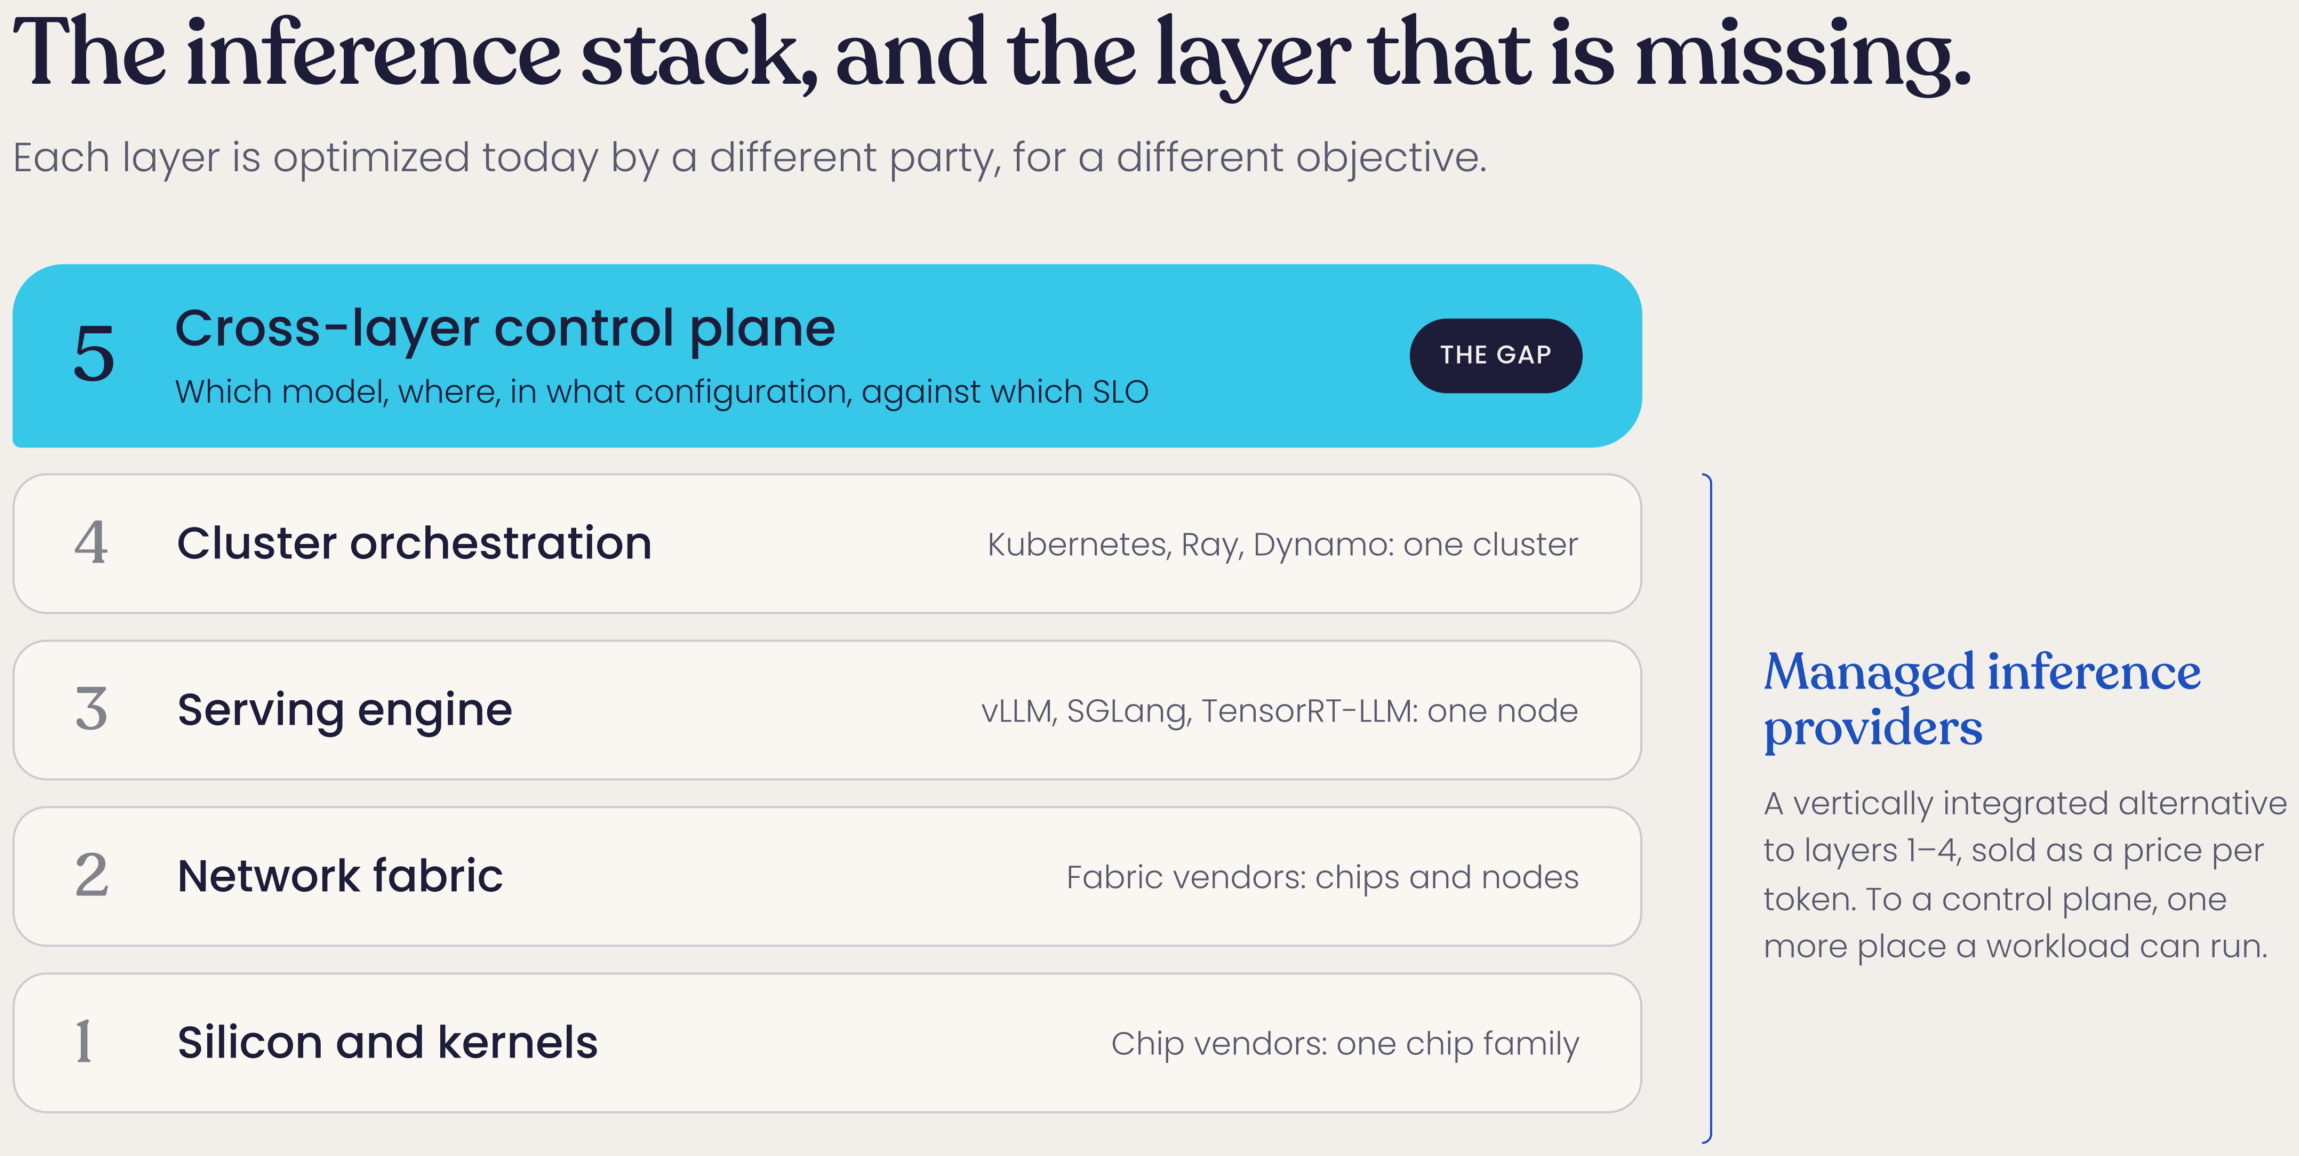
Our view is that enterprises will move from renting model access to owning their inference economics: the decisions that set what their AI costs, how it performs, and where it runs. Where it pays, they will own the fleet underneath too. The layer that makes this possible is the most important whitespace in AI infrastructure today.
Software-defined networking split networks into a control plane that decides where traffic goes and a data plane that moves it. Inference is heading the same way. The data plane is wherever tokens are produced: your own GPUs, a neocloud’s, a lab’s API. The control plane decides which model runs, on which hardware, in which region and configuration, against what quality bar.
Owning those decisions matters even when the tokens are rented: which model, which provider, which service tier. Owning the data plane is a narrower call, made workload by workload. For high-volume, high-stakes, repetitive workloads, the answer is increasingly a baseline fleet you control, plus rented capacity for spikes. Three forces are making that the right choice for a growing share of workloads: cost, control, and sovereignty.
Gartner expects inference to overtake training this year in spending on AI-optimized cloud infrastructure, $23.3 billion against $19 billion, and to reach 59 percent of that spending in 2027.3 For AI-native companies, inference efficiency flows straight to gross margin.
Falling token prices make the pressure worse, because cheaper inference invites more of it. Google now processes more than 3.2 quadrillion tokens a month, seven times as many as a year earlier.4 On OpenRouter, reasoning models went from a negligible share of tokens to more than half during 2025, and the average prompt grew fourfold.5 Total spend rises even as unit prices fall, so the savings come from deciding which tokens to spend and how the hardware spends them.
The price list does not predict the bill. Ito’s cheaper model consumed 2.5 times the tokens. Nous Research found the same pattern more broadly: on comparable tasks, open-weight reasoning models used 1.5 to 4 times as many tokens as closed ones, sometimes enough to cost more per query.6 It cuts the other way just as sharply. In a peer-reviewed study on a vulnerability-detection benchmark, a 4-billion-parameter open-weight model matched the best frontier model’s accuracy at one sixty-sixth of the cost per task.7 What matters is cost per task, and only the workload itself can measure it.
A company that rents its inference also rents the controls over it. It can pin a model version only until the provider retires it. OpenAI promises six months’ notice for generally available models and less for variants and previews. In July it shut down more than a dozen models, including GPT-5-Codex, and it scheduled fine-tuned GPT-4 and GPT-3.5 Turbo models that customers trained themselves for shutdown on October 23.8 Quality can change underneath the customer, too: in September 2025, Anthropic disclosed that three infrastructure bugs had intermittently degraded Claude’s responses for several weeks, hitting 16 percent of one model’s requests at the worst hour.9 Consistent low latency costs extra, through tiers such as OpenAI’s priority processing.8 In a survey by Broadcom, which sells private cloud through VMware, performance was cited as often as cost predictability as a reason to bring workloads back from public cloud.10
Gartner expects spending on sovereign cloud infrastructure to reach $80 billion in 2026, up 35.6 percent, as organizations outside the U.S. and China respond to rising geopolitical tension.11 Security and compliance was the top reason enterprises gave Broadcom for moving workloads off public cloud, cited by 51 percent.10 Banks are already running models on their own infrastructure. BNP Paribas serves open-source and Mistral models from GPUs in its own data centers, which it says keeps deployment “within the Group’s infrastructure, in compliance with data privacy requirements.” HSBC has signed a multi-year deal to self-host Mistral’s models on its internal systems.12 For a bank, an insurer, or a government agency, whether renting inference is allowed often comes before whether owning it is cheaper. And inference run in-house still needs a control plane on top.
Ownership pays off through the two levers from the opening examples.
The first is how the hardware runs a model. The best serving configuration changes as models, hardware, and traffic evolve, and there are too many options to search by hand. The Vidur project at Microsoft Research and Georgia Tech estimated that exhaustively testing configurations for one 70-billion-parameter model would take about 42,000 GPU-hours.13 NVIDIA’s own configuration tool, which claims up to 1.7 times the throughput of manual tuning, is built for initial setup.14 What happens after setup is the gap: traffic shifts, and each new model can invalidate the benchmarks, routing policies, and capacity plans built for the last one. Reconfiguring continuously as load shifted is where the second result’s 61 percent came from.2 Closing it takes a control loop: observe production, test alternatives, validate results, and adapt, without shipping any change that has not been proven safe.
Mixture-of-experts models cut both ways. MiniMax M3, the model Ito switched to, holds about 428 billion parameters but activates only about 23 billion per token.15 All the experts must sit in memory while only a few compute, so serving it well means spreading them across many GPUs, and for the largest models across nodes. That enlarges the configuration space, which favors a control loop. It also pushes the largest models toward rack-scale serving, which favors providers with scale for any workload that does not justify its own fleet.
The second lever is which model runs, and until recently there was little to choose from. Epoch AI puts the best open-weight models about four months behind the closed frontier this year. On cyber tasks, the UK AI Security Institute measures four to seven months, down from six to ten through most of 2025.16 Usage has followed: OpenRouter, which routes some 25 trillion tokens a week, found open-weight models at roughly a third of its traffic by late 2025.5
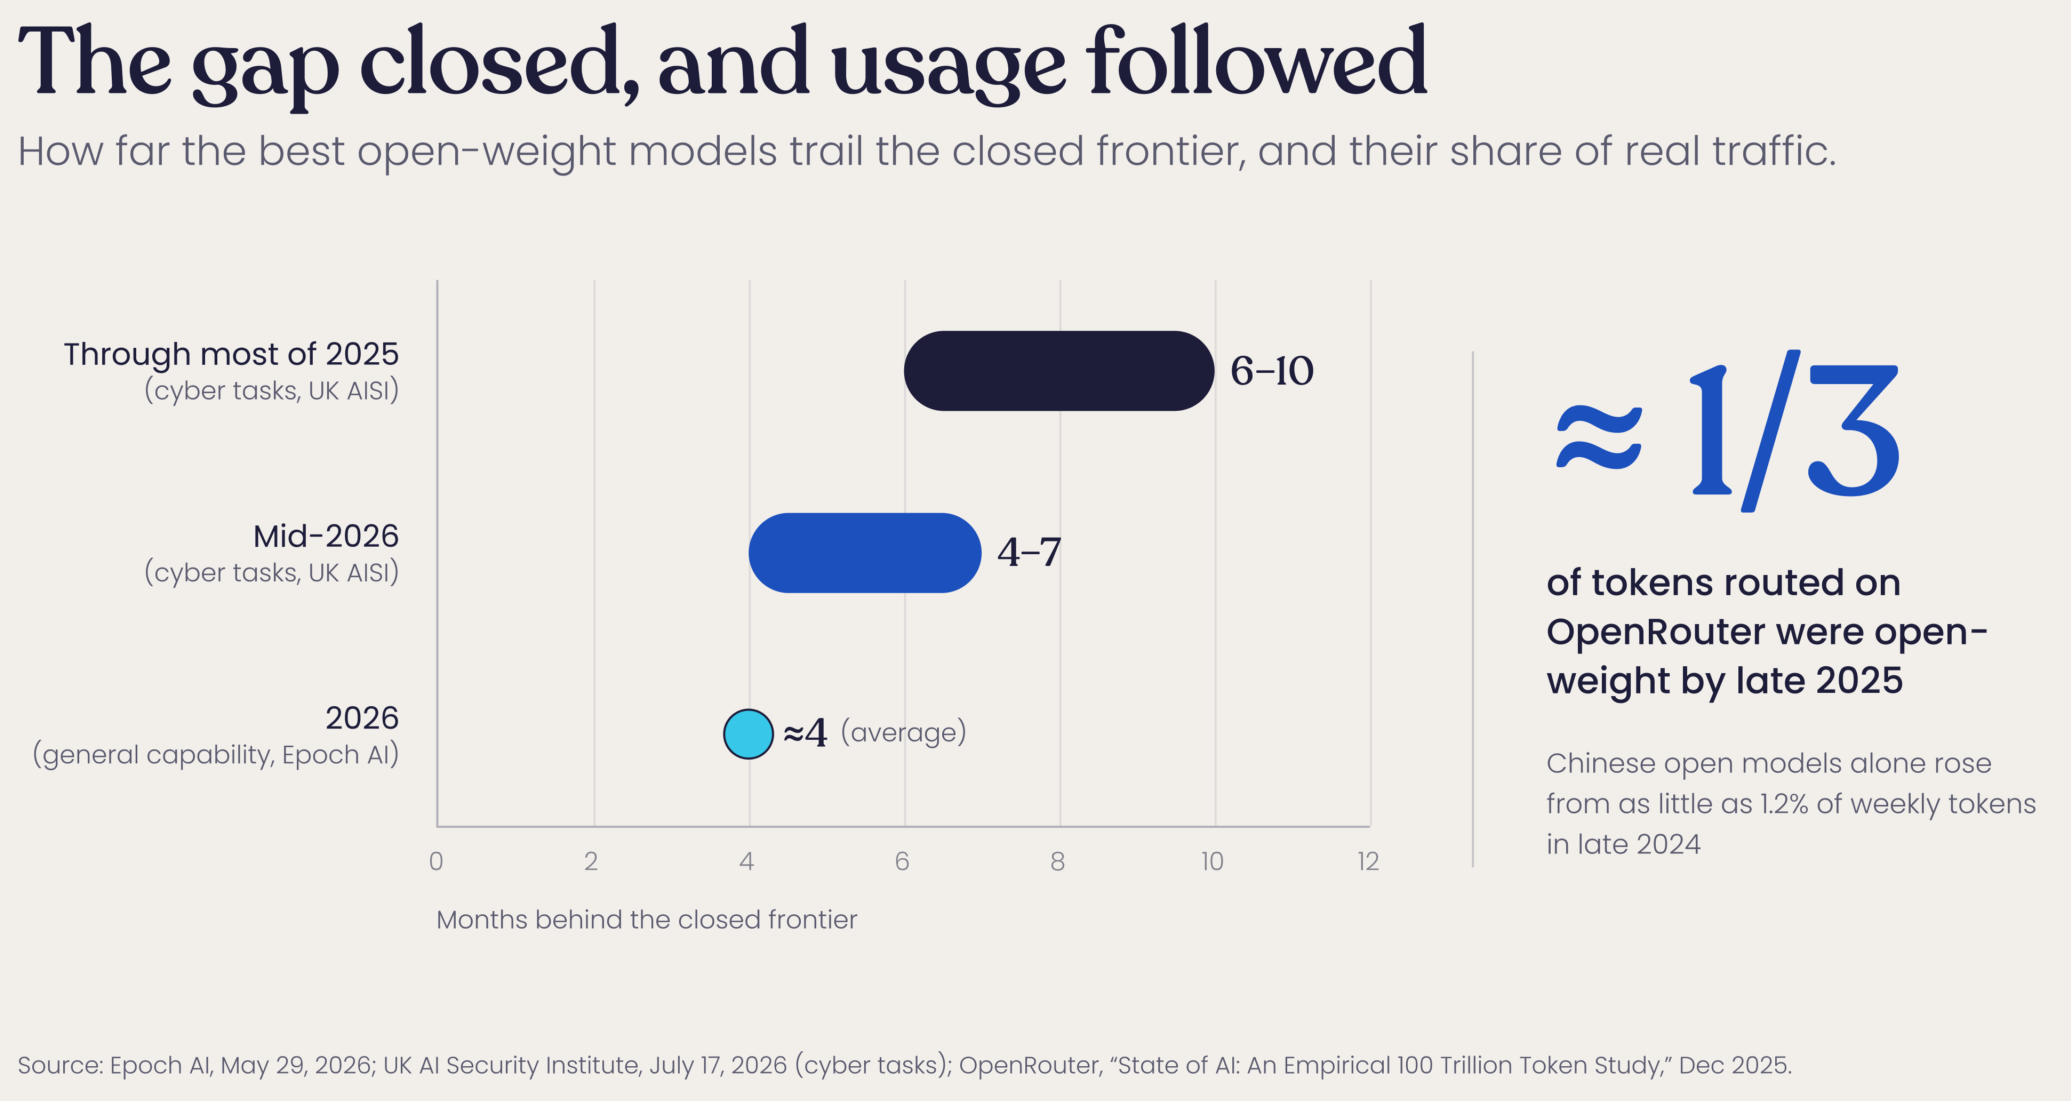
Figure 3. The capability gap narrowed, and open-weight models now carry a large share of real traffic.
The economics follow. Pinterest’s CEO says open-source models can reach similar performance at less than 10 percent of the cost of leading proprietary ones.17 Fireworks, one of the largest managed inference providers, says more than 95 percent of the tokens it serves come from models specialized on customers’ own data.18 Replit routes each task to the model best suited to it and, in its own testing, got the same output quality at 65 percent lower cost than the previous version of its Max Mode.19
The obvious objection is that none of this describes the average enterprise, and the data agree. IDC finds that 84 percent of spending on AI infrastructure goes to cloud and shared environments.20 Ramp’s spending data shows about 44 percent of U.S. businesses paying Anthropic, and about 40 percent paying OpenAI, for subscriptions or tokens.21 Accenture says about one organization in four runs open-weight and proprietary models in equal measure.22 Most inference is rented, and much of it should stay that way. The objection is right about today. It misses where the pressure is building.
The real split is by workload. Teams rent for capability-first work: the newest model, the hardest problem, the pilot. They run their own fleets for high-volume, stable work where the model is good enough but the bill, or the service level they owe their customers, is not. That category is a minority of workloads and a majority of the pain, and it grows with every pilot that reaches production. Broadcom’s survey of 1,800 IT leaders at large enterprises found 56 percent running or planning production inference on private cloud, and public-cloud use for those workloads down from 56 to 41 percent in a year.10 Rented capacity comes with someone else’s optimizer. Owned capacity comes with open-source engines and no one to keep them tuned.
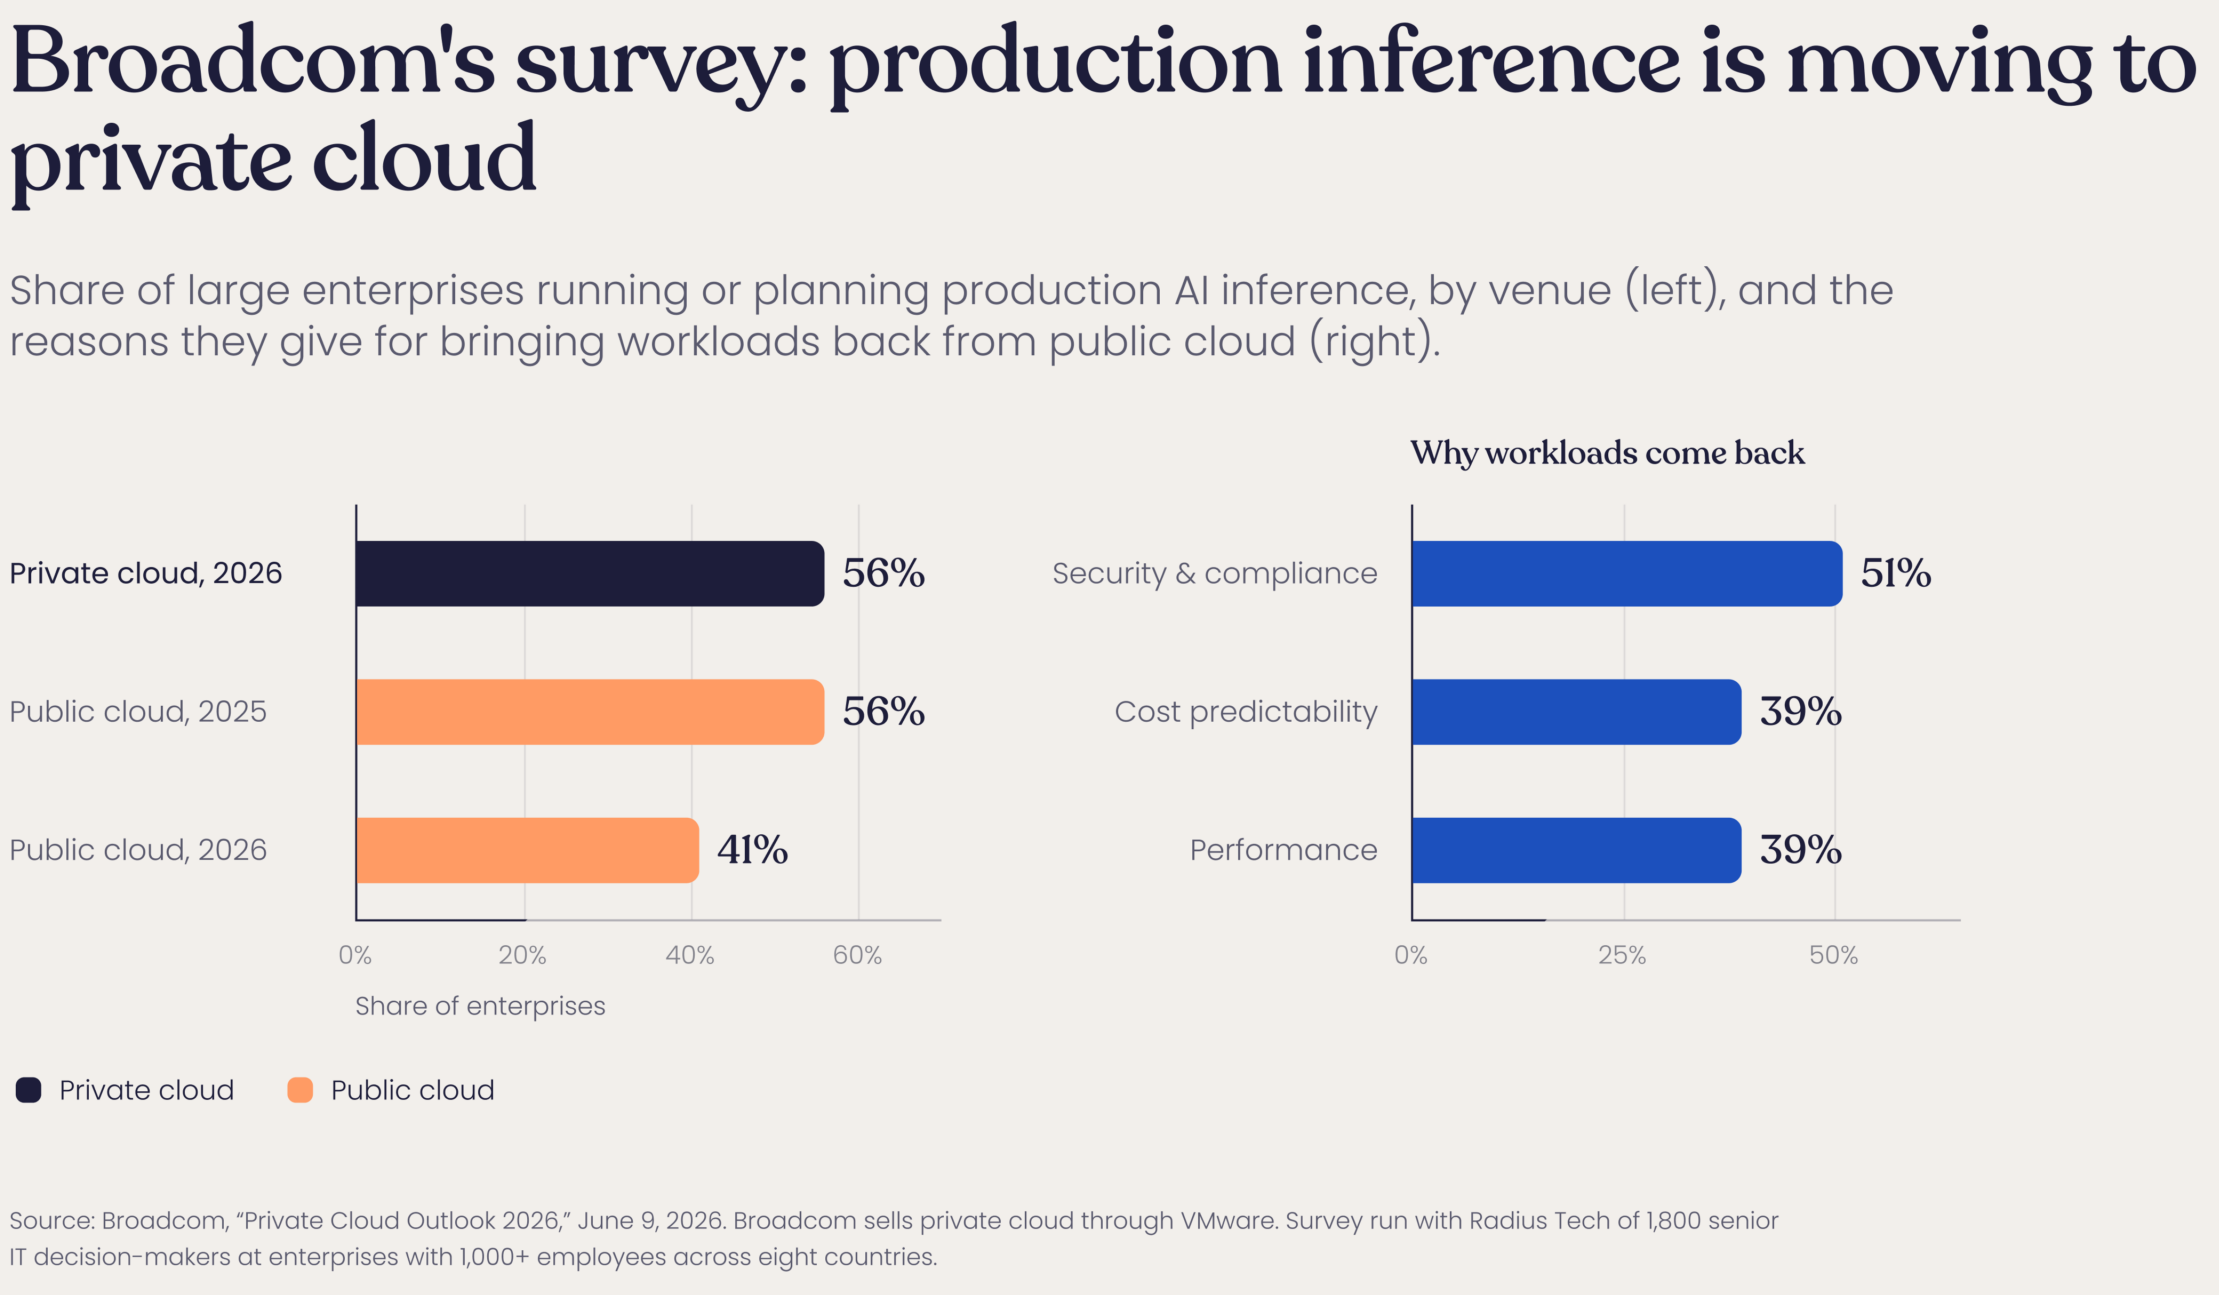
Figure 4. Where large enterprises run production inference, and why. Survey by Broadcom, which sells private cloud.
The market has made the case for a hybrid model: rent for experimentation and bursts; own the workloads where cost, latency, quality, or sovereignty justify control. But a hybrid fleet creates a new problem. Someone has to decide, continuously, what runs where- and prove that each change is safe.
That is the missing layer.
Stay Tuned for Part 2 of the Future of Inference Blog Series.
Sources and References
- Ito (Evan Marshall, CTO), “What we learned after moving 100B tokens/week to open-weight models,” July 13, 2026: Ito moved its test-runner agent, its largest LLM cost, from GPT-5.3-Codex to MiniMax M3; median LLM cost per pipeline run fell 55%; median step time rose from 23 to 29 minutes; failures rose from 2.4% to 4.5% of terminal states; the new model took 23% more agent turns and 2.5× the tokens; per-repository savings ranged from 81% to 13%; “Our invoices chose MiniMax.” ai
- Stojkovic et al. (University of Illinois Urbana-Champaign and Microsoft Azure Research), “DynamoLLM: Designing LLM Inference Clusters for Performance and Energy Efficiency,” HPCA 2025 (arXiv:2408.00741). The system reconfigures the number of instances, model parallelism, and GPU frequency, and “conserves 53% energy and 38% operational carbon emissions, and reduces 61% cost to the customer, while meeting the latency SLOs.” org
- Gartner, “Gartner Forecasts Worldwide AI-Optimized IaaS Spending to Grow 96% Through 2026,” Aug 10, 2026: “In 2026, global spending on inference ($23.3 billion) will surpass that of training ($19 billion)”; inference is 55% of AI-optimized IaaS spending in 2026 and is set to reach 59% in 2027. com
- Google, “I/O 2026: Welcome to the agentic Gemini era,” Sundar Pichai’s remarks, May 19, 2026: “Last year at I/O, that grew to roughly 480 trillion tokens. Fast forward to today, that number jumped 7x to over 3.2 quadrillion per month.” google
- OpenRouter, “State of AI: An Empirical 100 Trillion Token Study,” Dec 2025 (arXiv:2601.10088, Jan 2026): reasoning models grew from “a negligible slice of usage” in early 2025 to more than 50% of tokens; average prompt length grew “roughly fourfold from around 1.5K to over 6K” tokens; open-weight models reached “approximately one-third of usage by late 2025.” Weekly volume of 25 trillion tokens is OpenRouter’s figure, as reported by Forbes, July 18, 2026. ai arxiv.org
- Nous Research, “Measuring Thinking Efficiency in Reasoning Models: The Missing Benchmark,” Aug 14, 2025: “Open weight models use 1.5–4× more tokens than closed ones… making them sometimes more expensive per query despite lower per-token costs.” com
- Deininger and Slany, “Open or Frontier?”, Computers 15(9):623, Sept 16, 2026 (peer-reviewed). On PrimeVul, Gemma-3-4B tied Claude-Sonnet-5 at 0.653 balanced accuracy “at 1/66 of the cost per task” (“a 4-billion-parameter model matching the best frontier system’s quality at one sixty-sixth of the list price”), and a fine-tuned 125M-parameter detector outperformed all eight LLMs tested (0.765). The authors caution that at real-world prevalence, precision (2.3–8.2%) is too low for deployment for every model tested. com
- OpenAI API documentation, “Deprecations”: “Generally available models: At least 6 months” of notice; specialized variants such as chat and Codex models at least 3 months; preview models may be retired with “much shorter notice.” An April 22, 2026 notice listed 14 models and snapshots, including gpt-5-codex, for shutdown on July 23, 2026, and fine-tuned models including ft-gpt-4 and ft-gpt-3.5-turbo for shutdown on October 23, 2026. “Priority processing” offers “significantly lower and more consistent latency,” billed “at a premium to standard.” openai.com developers.openai.com
- Anthropic Engineering, “A postmortem of three recent issues,” Sept 17, 2025: “Between August and early September, three infrastructure bugs intermittently degraded Claude’s response quality”; “At the worst impacted hour on August 31, 16% of Sonnet 4 requests were affected.” com
- Broadcom, “Private Cloud Outlook 2026,” June 9, 2026. Broadcom sells private cloud through VMware; the survey was run by Radius Tech in partnership with Broadcom, among 1,800 senior IT decision-makers at enterprises with 1,000+ employees across eight countries: 56% running or planning production AI inference on private cloud; public-cloud use for the same workloads down from 56% to 41% year over year; top reasons for repatriation were security and compliance (51%), cost predictability (39%), and performance (39%). broadcom.com
- Gartner, “Gartner Says Worldwide Sovereign Cloud IaaS Spending Will Total $80 Billion in 2026,” Feb 9, 2026: up 35.6% from $59.3 billion in 2025; “As geopolitical tensions rise, organizations outside the U.S. and China are investing more in sovereign cloud IaaS…” com
- BNP Paribas, “BNP Paribas provides its businesses with an LLM as a Service platform to accelerate the industrialization of generative AI use cases,” June 5, 2025: the platform runs on “shared infrastructure hosted in the Group’s data centers” with GPUs and offers open-source and Mistral AI models; it “guarantees a secure deployment within the Group’s infrastructure, in compliance with data privacy requirements.” HSBC, “HSBC and Mistral AI join forces to accelerate AI adoption across global bank,” Dec 1, 2025: a multi-year partnership for “self-hosted AI models that operate on HSBC’s internal technology systems.” bnpparibas hsbc.com
- Agrawal et al. (Georgia Tech and Microsoft Research India), “Vidur: A Large-Scale Simulation Framework for LLM Inference,” MLSys 2024 (arXiv:2405.05465): a deployment-based search for the best LLaMA2-70B configuration “would have taken 42K GPU hours, costing approximately $218K.” org
- NVIDIA Dynamo documentation, “Finding Best Initial Configs using AIConfigurator”: “Up to 1.7x better throughput compared to manual configuration” (NVIDIA’s claim). nvidia.com
- MiniMax, MiniMax-M3 model card (Hugging Face): “~428B parameters and ~23B activated parameters”; 1M-token context. co
- Epoch AI, “Open models lag state-of-the-art closed models by 4 months,” May 29, 2026 (average gap since January 2026 on the Epoch Capabilities Index). UK AI Security Institute, “How far behind the frontier are leading open weight models on cyber?”, July 17, 2026: open-weight models “lag frontier closed models’ cyber capabilities by 4 to 7 months,” narrower than “the 6 to 10 months we measured through most of 2025”; AISI notes its setup likely slightly underestimates open-weight models. ai aisi.gov.uk
- Pinterest Engineering, “On the (re)-prioritization of open-source AI,” Dec 4, 2025. Foreword by CEO Bill Ready: open-source models can “achieve similar performance at less than 10% of the cost of leading, proprietary AI models.” com
- Fireworks AI, “Announcing our Series D and $1B ARR,” July 15, 2026: “More than 95% of those tokens come from models specialized on customers’ proprietary data and optimized for specific jobs.” ai
- Replit, “Intelligent Model Routing,” Aug 26, 2026: “In our testing, Intelligent Model Routing delivered the same output quality at 65% lower cost than the previous version of Max Mode.” com
- IDC, “Artificial Intelligence Infrastructure Spending to Reach $758Bn USD Mark by 2029, according to IDC,” Oct 28, 2025: AI infrastructure (compute and storage hardware) spending reached $82.0 billion in 2Q25; “Infrastructure deployed in cloud and shared environments accounts for 84.1% of the total spending in AI in 2Q25.” com
- Ramp AI Index, Aug 12, 2026 (July 2026 data): “43.5% of U.S. businesses paid for subscriptions or tokens from Anthropic”; OpenAI’s share was 39.7%. com
- Accenture Newsroom, “Accenture helps organizations unlock greater AI choice and control with open-weight models,” Aug 26, 2026 (updated Sept 28, 2026): “roughly one in four organizations now run a deliberate mix of open-weight and proprietary models in equal measure.” The post cites forthcoming Accenture research and gives no sample size. accenture.com